Guilty Until Proven Innocent
The bridge had been open long enough that people were starting to repeat themselves.
Something important was failing. Transactions were not completing. The application team had been through their application and found it running normally. The server team had gone through the operating system and found nothing wrong with it. My network engineers had walked the paths, the interfaces, and the devices in between, and found no fault there either.
Then somebody said it.
It has to be the network.
Nobody had traced a transaction. Nobody had established where in the chain the failure was occurring, or even whether it was occurring before or after a connection was established. What had happened was narrower than a diagnosis: every team with a component had checked its component and reported it clean, and the network was the last name on the list.
That sentence is not a finding. It is a residue.
Three correct answers
The easy read of that scene is that somebody was not looking hard enough, or was protecting a team. That read is wrong, and it is worth killing early, because believing it makes the actual problem invisible.
Every one of those three answers was correct.
The application was healthy. It was doing exactly what it had been built to do. The operating system was healthy; there was nothing wrong with the host as a host. And the network was healthy in the only sense a network can be: it was forwarding what it had been handed, to the place it had been told to send it.
Three teams. Three accurate reports. None of them answered the question, because none of them had been asked it. Each had been asked whether its own component was working, and each had answered that question honestly.
A team’s diagnostic scope ends at the edge of what it owns. That edge is where the looking stops. It is not where the fault stops.
A timeout is not a location
Part of why that bridge stalled is that the evidence in the room was weaker than everyone believed it was.
Consider what has to succeed for a single transaction to complete. A name resolves. The host consults its own table, selects a route, and picks an interface. A session attempts to establish—a SYN leaves, a SYN-ACK comes back, an ACK completes the handshake. If the connection is encrypted, certificate and cipher negotiation follow. The request crosses whatever sits in the path, a firewall and a load balancer among them, and reaches a listener. The application accepts it, hands the work to a worker, calls a database or an API, and waits on that dependency. A response is built and returned along the same path.
A client-side timeout can be produced by a failure at any point in that sequence, and it looks the same to the user at every one of them.
A timeout tells you a transaction did not finish. It does not tell you where.
The evidence brought to rebut it is just as thin in the other direction. An echo reply proves that an ICMP echo request and its reply traversed a path. It does not prove the port you care about is open, or that anything is listening on it. It does not prove negotiation completes, or that latency is tolerable for the workload. It does not prove the application on the far end has a worker free to answer, or that the database behind it is answering at all.
A completed connection proves connectivity. Connectivity is not health.
Two updates, one weekend
What had actually happened that weekend was not one change. It was two, and they had not gone in at the same moment.
An application update and an operating system update had landed across the same maintenance period, close enough to be related and far enough apart that no single event sat at the front of the failure. Both were ordinary iterative updates from their manufacturers. Both were installed by competent engineers. Both were validated the way updates get validated, which is to say against an environment that was not production.
Neither update was defective. What changed was the behavior of the system the two of them formed.
That is why the component checks came back clean. Every team was looking for something wrong inside its own boundary, and there was nothing wrong inside anyone’s boundary.
The separation did further damage to the investigation. A change that goes in and is followed by nothing gets acquitted. When the failure surfaces after the second change, the second change becomes the suspect and the first one has already been cleared. This condition required both, and nobody’s reasoning was holding both at once.
So I stopped checking components and started following the transaction.
That meant understanding what the failing application was actually trying to do—not in the abstract, but concretely: what it needed, and where that lived. It fed a second application, which fed a third. I traced the chain back through all three until I reached the point where the work actually terminated, and then asked the only question that mattered. What does this need to reach, and which path is the host using to get there?
The answer was inside the server.
Here is the part that gets skipped, and it is worth being precise about. Routing does not begin at the router. Before a packet reaches a switch, before anything in the network has an opinion about it, the operating system has consulted its own table and made a series of decisions: whether the destination is local or remote, which interface will carry the traffic, which next hop receives it, and which route wins when more than one of them matches. Those decisions are made on the host. The network never sees the alternatives the host rejected.
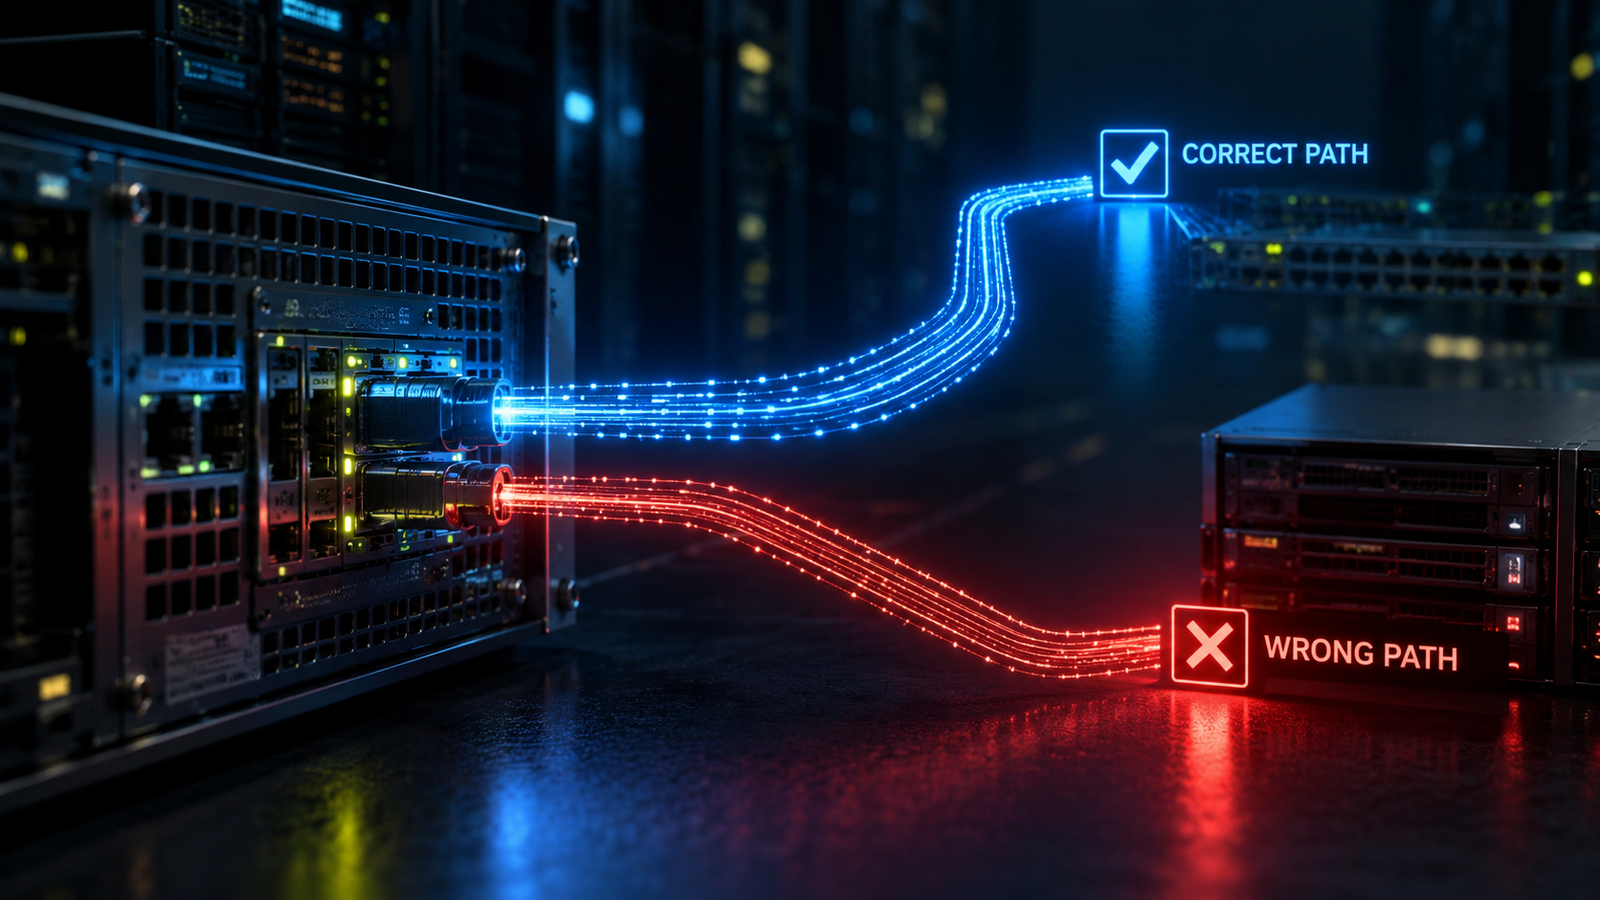
That server had more than one usable interface. The application’s dependency was reachable through one specific segment, and the host was sending its traffic out a different one. From the operating system’s point of view nothing about that was an error. A route matched, the interface was up, the traffic left. The host had no way to know that this application’s dependency lived somewhere the chosen path could not reach, because nothing had ever told it.
The network was forwarding it faithfully. It was forwarding it to the wrong place, because that is where it had been handed.
One routing change on the server. No router touched, no switch touched, no firewall touched.
Nobody designed it to work
Which raises something that took longer to sit with than the fix took to make.
The previous configuration should not have worked either.
The host had standard routing. No custom routes, nothing anyone had gotten wrong—simply the routing a server has when nobody has told it otherwise. What the application needed in order to do its work inside the enterprise’s design was a route that had never been configured. The requirement and the configuration had not matched from the beginning.
The theory I still hold is that the operating system, at the patch level it had been running, permitted the routing behavior the application wanted, and that the patches closed it off. The application’s own update appears to have hardened its requirement across the same stretch of time, becoming more insistent about the path it needed as the host stopped tolerating it. Two manufacturers, working independently, tightened opposite ends of the same transaction inside the same few weeks.
That is a theory. I never confirmed it.
The diagnosis was not a theory. The routing table on that host, the interface it was selecting, and the fact that the application’s dependency was not reachable that way were all observed. Only the history is inference.
The chronology is worse than it sounds, because a patch level is not a date. My network team ran a strict n-2. The application and operating system teams patched on their own judgment rather than a fixed cadence. Whatever decision closed that permissive behavior was made by an engineer at a manufacturer at a point I had no visibility into, and it reached that environment whenever those teams happened to bring it. The event that surfaces a failure and the decision that caused it can be a year apart.
What I did know was that the system had been depending on behavior nobody had chosen.
Production accumulates that. A default lands on the result somebody wanted. Two implementation details line up. A dependency nobody wrote down survives years of people assuming it was designed.
That has an unpleasant implication for the first question anybody asks in an incident.
What changed?
It is the right instinct and it is enormously productive. Its blind spot is the assumption that the answer is one thing. It finds changes. It does not find the dependency a change exposed, and when the exposure took two changes arriving separately, each one gets examined alone and cleared.
It also disposes of the most reassuring sentence in operations. It worked before. That is not evidence the configuration was ever right. It is evidence that something was making up the difference.
We went looking after that. Routing across the server farm was re-examined, host by host, for hosts whose behavior depended on a route nobody had configured.
We found them.
That is what turned an incident into something worth writing down. One host in that state is an oddity. A farm with more of them is not an accident of one server. It is what the environment produced while everyone was operating it correctly.
The seam is not on the org chart
Go back to the three clean reports, because that is the part of this that generalizes.
They were not a failure of diligence. They were a product of how the work is divided. Ownership defines what each team monitors, what it is paged for, and what it is measured on, and therefore what it looks at when something breaks. Those boundaries are the reason a large environment can be operated at all. They are also the reason this fault survived three competent investigations. It did not live inside a component. It lived in the seam between two of them.
Nothing watches a seam. No monitor is pointed at it, no team is paged for it, no dashboard has a panel for the interaction between an application update and an operating system update that were both correct. A seam has no owner because it is not a thing. It is a relationship between things that have owners.
Which is why finding it required someone who had worked both sides of one. Not brilliance—vantage. Someone whose view did not stop at the line the org chart drew, who could read a host’s routing table and a routing decision as one subject rather than two departments.
Specialization has no reason to preserve that vantage, and its absence is not an oversight. It is the design working as intended. Divide a large environment into components, give each one a team that knows it deeply, and every component gets run better than a generalist could manage. Cross-boundary vantage is not something the structure produces. It has to be put there deliberately, and it is hard to defend, because it is the one role that cannot point to a component it owns.
The teams get sharper. The seams get quieter, in the specific way that any place nobody is looking at is quiet.
A transaction crosses every boundary in the system. The investigation almost never does.
Discover more from At Ground Level
Subscribe to get the latest posts sent to your email.